On-Premise LLM Deployment & Enterprise RAG Solution with NVIDIA GPU Servers. https://ailocallm.com/
As enterprises accelerate Generative AI adoption, data privacy, IP protection, and compliance remain top concerns. Sending proprietary knowledge bases, financial records, customer data, and source code to public cloud AI APIs introduces severe data leakage risks.
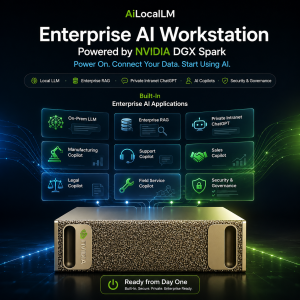
AiLocalLM provides an end-to-end on-premise LLM deployment and private RAG system engineered for enterprise governance. Powered by high-performance NVIDIA GPU servers, AiLocalLM brings autonomous, secure, and compliant Generative AI directly to your corporate data center, private cloud, or air-gapped infrastructure.

Why Enterprises Choose On-Premise LLM Deployment over Cloud AI
Modern enterprises in healthcare, finance, defense, semiconductor manufacturing, and government institutions require absolute control over their intelligence stack.
Implementing a self-hosted enterprise LLM infrastructure addresses critical enterprise challenges:
-
Complete Data Sovereignty: Your data never leaves your local network. Zero API calls to external cloud providers like OpenAI or Anthropic.
-
Regulatory & Compliance Readiness: Built to support strict regulatory frameworks including HIPAA, SOC 2 Type II, GDPR, and ISO 27001.
-
Air-Gapped Security: Fully operable in 100% disconnected (air-gapped) environments with zero outbound internet access required.
-
Unmatched Query Latency: Local vector databases and NVIDIA GPU acceleration eliminate network transmission lag for real-time inference.
-
Fixed TCO & Cost Predictability: Avoid unpredictable monthly cloud token billing; pay once for infrastructure and scale processing indefinitely.
Enterprise RAG Solution: Secure Knowledge Base Intelligence
Retrieval-Augmented Generation (RAG) bridges the gap between static LLM reasoning and dynamic enterprise knowledge. AiLocalLM delivers a private RAG system designed for complex file structures and fine-grained access control.
-
Universal Enterprise Knowledge Connectors
Effortlessly ingest PDF manuals, Word documents, Confluence pages, SharePoint repositories, SQL databases, and internal wikis into local vector storage.
-
Role-Based Access Control (RBAC) Integration
Integrate seamlessly with Active Directory, LDAP, or SSO. Users only receive AI-generated insights derived from documents they are explicitly authorized to view.
-
Precise Source Attribution & Zero Hallucination
Every response generated by the local LLM server for business cites precise internal source documents, page numbers, and snippet passages for instantaneous auditing.
NVIDIA GPU Acceleration & Hardware Architecture
Hardware performance determines enterprise LLM throughput. AiLocalLM is optimized specifically for NVIDIA GPU servers for LLM and enterprise RAG workloads.
| NVIDIA GPU Architecture | Targeted Enterprise Workloads | Processing Capabilities |
| NVIDIA H100 / H200 | Large Enterprise AI Clusters & Multi-Tenant Deployment | High-throughput inferencing for 70B+ LLMs and fine-tuning. |
| NVIDIA L40S / L40 | Enterprise RAG Server & Multimodal AI | Optimal balance for vector processing, document parsing, and 13B–70B models. |
| NVIDIA RTX 6000 Ada | Departmental On-Premise LLM Appliances | Quiet workstation/edge deployment for isolated RAG search. |
Optimized Local LLM Stack for Enterprise
-
Inference Engines: vLLM, TensorRT-LLM, and Ollama enterprise runtime.
-
Vector Engines: Milvus, Qdrant, and Chroma vector databases with GPU acceleration.
-
Open Model Flexibility: Native support for Llama 3, DeepSeek, Mistral, Qwen, and custom domain fine-tuned models.
Frequently Asked Questions (FAQ)
-
What is an on-premise LLM deployment?
An on-premise LLM deployment installs and runs Large Language Models locally on a company’s internal servers or private data center, ensuring sensitive business data remains inside the corporate firewall.
-
How does an enterprise RAG solution protect internal data?
An enterprise RAG solution retrieves information from local vector databases without sending documents to public cloud AI APIs. All indexing, vector embedding, and response generation occur within your secure network.
-
Why is a private RAG system necessary for regulated industries?
Regulated sectors such as finance, healthcare, and government must comply with strict data privacy laws (SOC2, HIPAA). A private RAG system prevents confidential records, source code, and patient data from leaking to third-party providers.
-
Which NVIDIA GPU server for LLM is best for local AI?
The choice depends on model size and user concurrency. NVIDIA L40S and RTX 6000 Ada offer excellent price-performance for departmental RAG, while NVIDIA H100/H200 servers suit large-scale enterprise deployments.
-
What are the benefits of a local LLM server for business compared to cloud APIs?
A local LLM server for business provides predictable fixed costs, lower inference latency, complete customization, fine-grained access control, and guaranteed compliance.
-
Can air-gapped LLM deployment work without an internet connection?
Yes. AiLocalLM supports complete air-gapped LLM deployment, allowing your AI stack to parse, search, and generate responses in completely isolated environments.
-
How does a self-hosted enterprise LLM integrate with existing IT systems?
AiLocalLM features open RESTful APIs, Active Directory/SSO integration, and pre-built connectors for platforms like SharePoint, Confluence, and custom SQL databases.
-
What hardware is required for an on-premise RAG server with NVIDIA GPUs?
A typical entry-level configuration starts with an enterprise rack server equipped with at least one NVIDIA L40S or RTX 6000 Ada GPU, 128GB+ System RAM, and NVMe SSD storage.
-
What open-source models work with the best local LLM stack for enterprise?
AiLocalLM supports top-tier open-weight models including Llama 3, DeepSeek-R1/V3, Mistral, and specialized enterprise fine-tuned models.
-
How long does it take to deploy AiLocalLM on-premise?
Standard deployment on pre-qualified NVIDIA GPU hardware typically takes 1 to 3 business days, including knowledge base indexing and role-based access setup.
Schedule Your On-Premise LLM Consultation
Bring autonomous, secure, and compliant Generative AI to your enterprise. Visit AiLocalLM (https://www.ailocal-lm.com/) today to request a architecture blueprint, schedule a private benchmark demo, or speak with our AI infrastructure team.